Improve and governyour AI agents
Traigent scores AI agents per KPIs the business answers for, recommends and drives improvements, and keeps an
audit‑ready record of it all.
In a few hours our agent had 10% better accuracy at 70% lower cost. Traigent’s ledger proved it.”
One record, three people who need it
CTO / Head of AI
One fleet view, and a ranked list of what needs attention and why.
Engineering leads
Before/after comparisons under the same conditions, with cost and latency kept separate.
Risk & compliance
A recorded evidence trail per agent. It is not a regulatory certification.
Four parts, one evidence trail
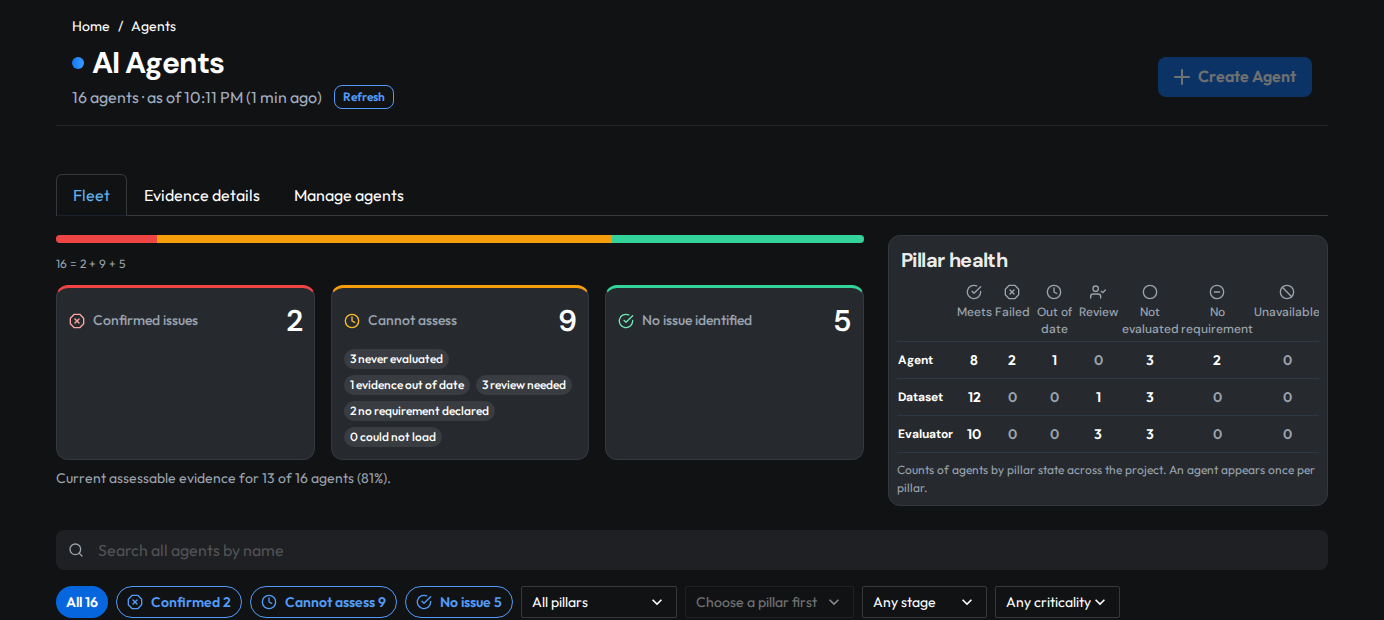
1. Fleet view
Status of every agent across agent, evaluation dataset and evaluator, ranked by what needs attention.
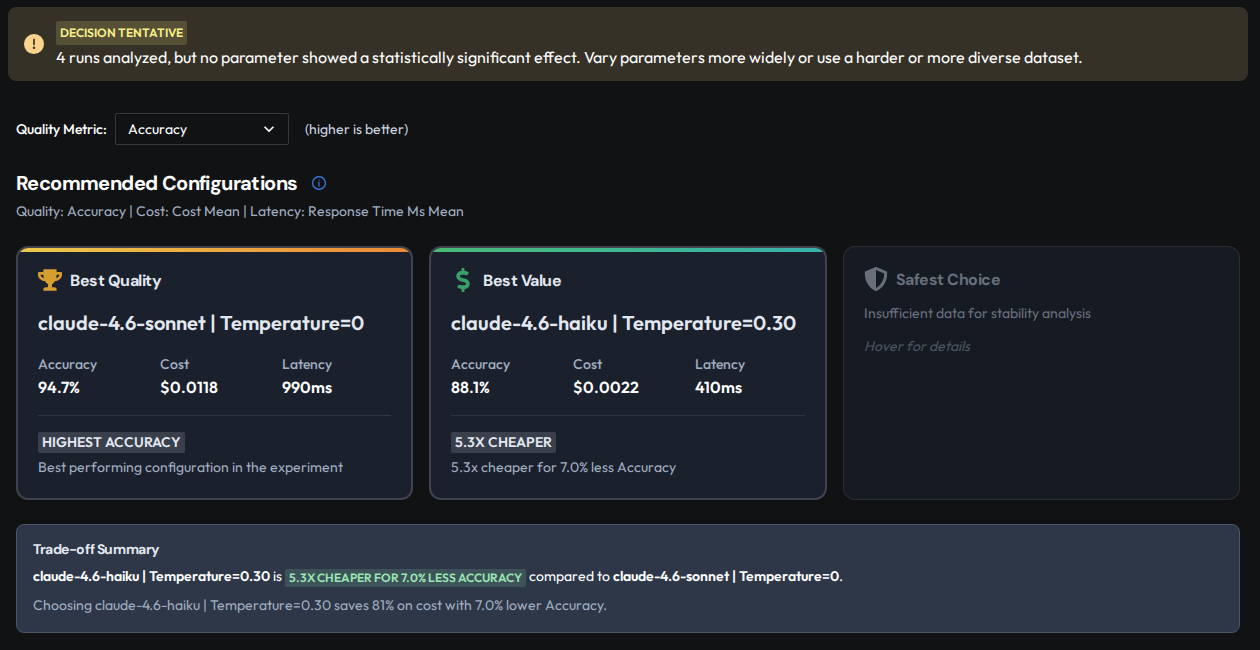
2. Scorecard & comparison
Baseline vs candidate on the same dataset and evaluator; each requirement is answered with its basis.
3. Next step
Traigent's recommended experiment. Your coding agent picks it up; Traigent records the result.
4. Evidence record
Measurement history per agent, ready for review.
Traigent recommends. Your team runs. Traigent records.
- 1
Traigent recommends the next step.
- 2
Your coding agent picks it up and runs it in your environment.
- 3
Traigent records what was measured.
- 4
The team reviews the result.
What stays with you, and what Traigent sees
Stays in your environment
Example inputs, prompts and model responses; model calls use your own API keys. Prompts stay local, except the prompt variants you choose to tune, which are sent as configuration values.
Sent to Traigent
Configuration values (including prompt variants being tuned), scores and run metadata.
Applies to the SDK optimization flow. Hosted datasets are a separate opt-in that stores dataset text in Traigent. The SDK can also run fully offline.
Start where you are
Three steps, each worth more than the last. Go as far as is useful to you.
Scorecard
You give: eight yes/partly/no answers. Nothing is sent.
You get: a score for each of four areas and where to look first.
Offline audit
You give: your own agent, run by your coding assistant. No Traigent account.
You get: a local baseline for quality, cost and latency, and a review of whether you can compare options fairly.
Optimize
You give: a Traigent account (new accounts get 10 days of portal access) or a call.
You get: recommended improvements, same-conditions comparisons, and a recorded trail of each change.
Paid POC
1–3 of your agents, over 2 months, credited to the year-1 license. Talk to us for pricing. Baselines, an evaluator check, recommended next steps with recorded results, and an executive readout.
Is your AI agent safe to update, and are you overpaying for it?
Answer eight questions in two minutes. The scorecard keeps your answers in your browser.